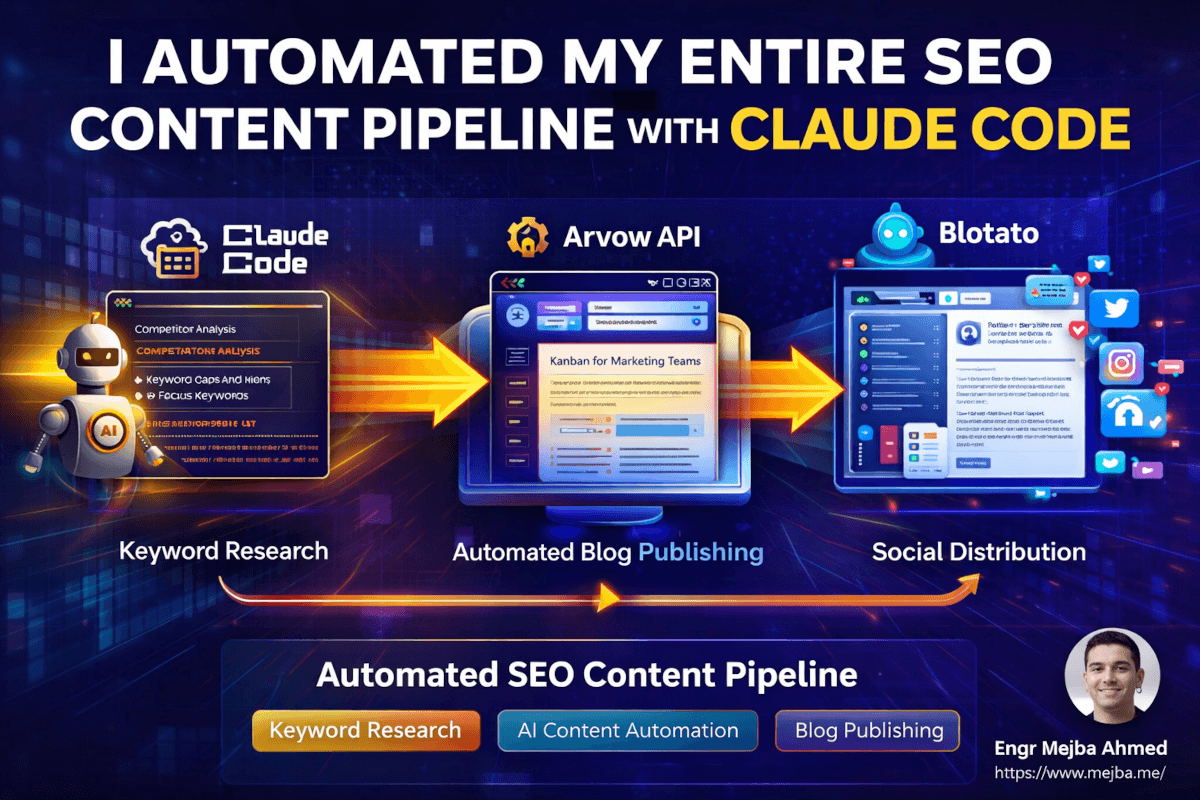
I automated my SEO content pipeline with Claude Code, and it nearly destroyed my site's search presence before it rebuilt it. Both halves of that sentence are measured, not metaphorical: Google Search Console shows my indexed pages collapsing from 7,103 on April 14, 2026 to 1,690 by May 4, with peak traffic of 859 clicks a day falling to nearly zero. The recovery was also automated, a Claude Code pipeline that surgically rewrote 84 posts with backup scripts, resume manifests, and a hard verification gate. So this is not another post promising a content machine that prints rankings. It is the honest version, with numbers, of what SEO automation actually does: it amplifies whatever your content operation already is, including its flaws.
The crash: what naive automation actually produced
The tempting version of "automate SEO content with Claude Code" is volume: generate briefs, generate drafts, publish on schedule. I ran variations of that, and the failure arrived through three compounding problems I can date precisely.
First, templated sameness. Batch generation from one skeleton meant dozens of posts opened with the same heading pattern, closed with a byte-identical call-to-action block, and recycled section headings across the corpus. My later corpus audit found 503 of 581 posts opening with an H2 that duplicated the title. Each post looked fine alone; in aggregate, Google read the pattern for what it was.
Second, fabrication at scale. One automated content vertical on my site produced 36 news articles whose sources I later audited: 30 of the 36 cited sources returned 404s, and metrics in the copy could not be verified anywhere. I unpublished all 36. That audit changed how I think about generation more than any ranking chart, because the pipeline had not just written badly, it had confidently invented, and published, at scale.
Third, technical signals rotted by side effects. My sitemap reported lastmod from updated_at, so every admin edit and observer touch pushed a third of my URLs to "modified today," daily. Google reads that as gamed freshness. Add a locale cookie being set on bot visits (shattering CDN cache efficiency) and unblocked JSON endpoints getting indexed, and the crash was overdetermined.
The lesson that reframed everything: search engines are running a fabrication detector and a pattern detector against your whole corpus. Automation that increases output while degrading distinctiveness and truthfulness is not neutral. It is compounding liability.
The pipeline that fixed it: automate remediation, not volume
The recovery pipeline is the thing actually worth copying. Its unit of work is not "new post," it is "verified improvement to an existing post," and every stage is a real script or artifact on my server.
Stage 1: Corpus inventory. A Claude Code session queries the production database read-only and emits a structured report per post: word counts, heading structure, internal links in and out, duplicate-title patterns, cannibalizing pairs. This is what surfaced the 503-post heading bug and the 440 posts with zero inbound links, numbers I would never have found hand-auditing 581 posts.
Stage 2: Research and triage with parallel agents. Ten research agents each take a slice of the corpus and score posts against the queries they should serve, flagging which deserve rewrites and what real evidence exists for each. The parallel structure is the only way corpus-scale work fits in context windows; the architecture is documented in my agent swarm post.
Stage 3: Surgical rewrites with assigned evidence. Rewrite agents each own a fixed set of post IDs, and every assignment names the evidence the rewrite must be grounded in: my actual configs, real project logs, verifiable facts. Third-party claims get web-verified or cut. This constraint, evidence assignment, is the anti-fabrication mechanism, and it exists because of those 36 purged articles.
Stage 4: A deterministic verify gate. Before anything ships, a Python verifier checks every draft: structure rules (no heading that repeats the title, no H1 in the body), every internal link validated against a slug index, banned-phrase scans, minimum quality scores. Fluent-but-wrong work fails here, which matters because agent errors are correlated and human review fatigues by post 40 of 84.
Stage 5: Transactional application with escape hatches. An apply script backs up the full database row to a JSON file, wraps the update in a transaction, and touches exactly one post by ID. A manifest file records every post's state, updated per unit of work, so when sessions died mid-batch at usage limits (twice, during my longest run), recovery was reading the manifest and resuming from PENDING. The full 84-post project ran across seven batches with zero lost work, and average internal quality scores moved from roughly 75 to 86.
Stage 6: Standing automated checks. The maintenance layer runs without me: model observers regenerate the sitemap when content changes, and scheduled Claude Code routines run recurring SEO audits against the live site, the setup in my SEO checks with Claude Code routines post. Automation's best role is the boring vigilance humans skip.
The numbers, and what they honestly mean
What I can state from my own dashboards: the crash bottomed at 1,690 indexed pages in early May 2026; the technical fixes (sitemap lastmod from published_at, cookie behavior, X-Robots-Tag on API routes) shipped May 4; Google began revalidating within days; and recovery of indexation happened over the following weeks, on the multi-week timescale Google's trust rebuilding actually takes. The content-quality pipeline above ran through that window and continues now.
What I will not claim: that any single rewrite "10x'd traffic," or that the pipeline guarantees rankings. Attribution across a period that included both technical fixes and content remediation is genuinely murky, and anyone selling you a cleaner causality story about their own automation is selling.
What I would tell you to build
If you want to automate SEO content with Claude Code, build the pipeline in this order, which is roughly the reverse of what the tutorials teach:
- The audit first. Corpus inventory scripts that tell you what you actually have. Cheap, read-only, immediately revealing.
- The verifier second. Your quality gate, as code, before any agent writes a word. Every rule in mine exists because something shipped without it.
- Remediation third. Rewrites of existing underperformers, grounded in evidence you assign, applied transactionally with backups. This is where the compounding returns live, because improving indexed URLs beats minting ignored ones.
- Generation last, if at all. And only with the evidence-assignment constraint, because a generator without assigned truth converges on confident invention. Purpose-built tooling like a programmatic SEO skill fits here, after the safety net exists, and my broader Claude SEO toolkit covers the supporting tools.
One infrastructural note that saved the whole operation: durable state outside the AI. Manifests, backups, and memory files meant no session death, usage limit, or model quirk could lose work. That discipline is its own topic, covered in my six levels of Claude Code memory.
The uncomfortable summary is that the most valuable thing my SEO automation does is say no: no to publishing unverified claims, no to templated sameness, no to touching a row without a backup. The generation part was always easy. The judgment part is the pipeline.
I now run this same audit-verify-remediate process for client sites, from Laravel platforms to WordPress builds, with the same rule I apply to my own: measured claims only. If your site's content operation needs the honest version of SEO automation, my services page is where to start.